5 MIN READ
The data classification conversation has been running on repeat since 2010, and it keeps producing the same four tier schema every time. Public, internal, confidential, restricted, some variation on the theme. The schema lives in a SharePoint page that nobody reads, the labels get applied to a small fraction of the actual data assets in most organisations, and the audit finds the gap the same way every year. The 2026 version of this debate is a debate nobody is going to win, because the question being asked is the wrong question.
Lineage worth knowing. The Microsoft 2007 white paper on data classification became the de facto reference, and most enterprise schemas have been a downstream remix of it ever since. The 2018 GDPR enforcement wave added regulatory teeth, the 2023 SEC cyber disclosure rules added the executive reporting angle, and the 2025 EU AI Act added another layer. Three regulatory moments, the same schema, the same gap between the policy document and the actual data. The answer is not a better schema.
Why the debate goes nowhere
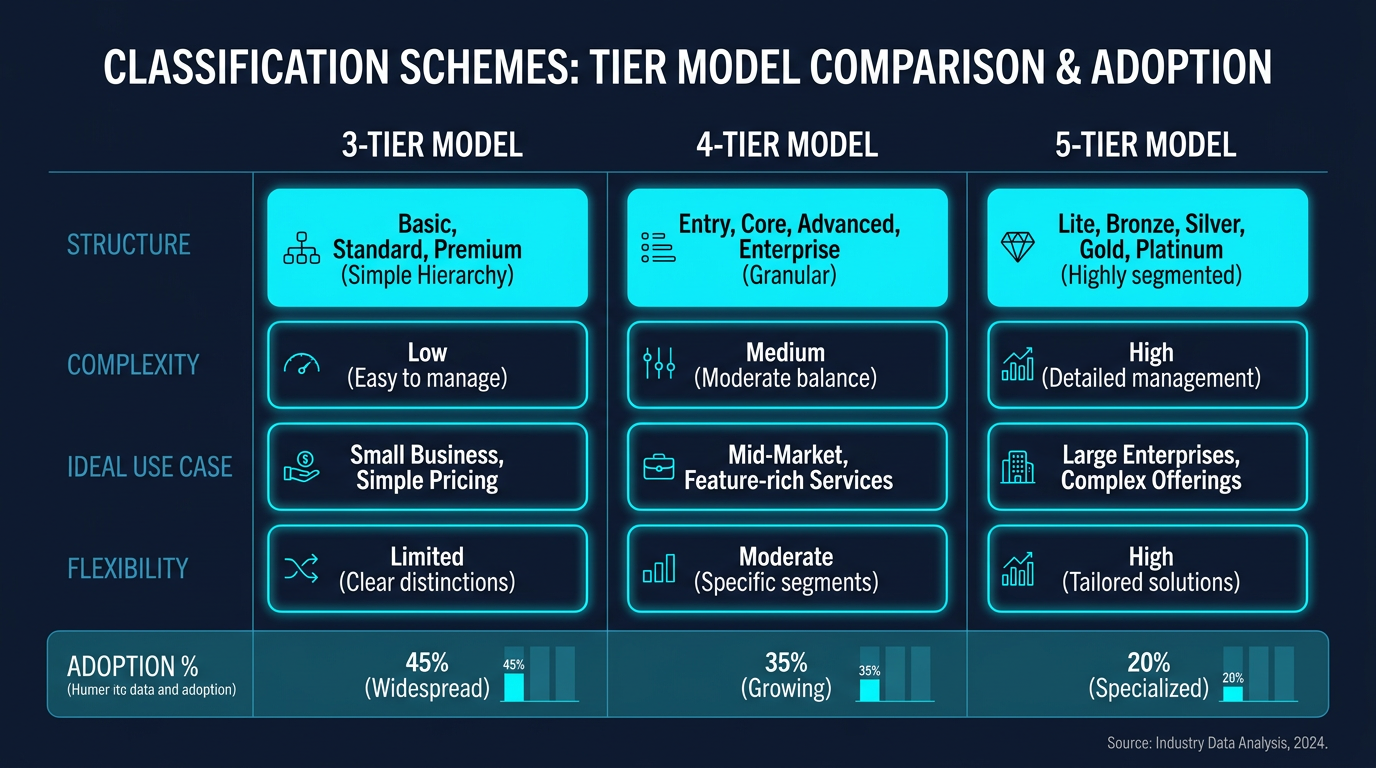
Four teams sit at the table, and each one is answering a different question. The security org argues about risk exposure, the data platform org argues about the operational cost of labelling, the privacy office argues about the regulatory requirement, and the legal team argues about the contractual obligation. They use the same words (data, classification, label) to mean four different things, and the convergence they keep promising is the convergence they keep failing to deliver. The way to break the deadlock is a smaller conversation, not a larger one. Pick the minimum useful schema and ship it. Three categories: public, internal, restricted. Nothing more. Whatever the data platform org can actually maintain, the audit can actually validate.
What the practical minimum looks like
Three categories, defined tight, enforced through the systems that already exist. Public covers anything the organisation has decided to publish, from the press releases the marketing org has approved to the documentation the developer relations team has written. Internal covers the data the business uses to run itself, from the customer records the support org needs to the financial data the finance team reconciles against. Restricted covers anything with a regulatory or contractual sensitivity, from authentication credentials to payment data to health records to the personal data the GDPR enumerates. Three categories handles the day to day decisions, the audit, the regulatory framework, and the contractual obligation. The orgs that try to do more end up with a schema nobody uses, labels nobody maintains, and the audit finding that the labels are out of date within the quarter.
What to skip
Four moves that look like progress and tend to eat the same budget. The seven tier schema is the compliance team’s favourite, a spreadsheet the data team updates the week before the audit and forgets the week after. The per row label is the privacy team’s dream, but the operational cost of getting the data platform team to apply it is high enough that the data team will push back until the label gets deprioritised. The auto classification tool gets sold as a silver bullet, and the realistic accuracy on the training data leaves the wrong label on a meaningful share of the most sensitive records in the published benchmarks. The annual relabelling exercise is a chore everyone schedules and nobody wants, the kind the data team treats as a tax, and the kind that produces labels out of date within three months. The security org will keep being sold these. The platform team will keep pushing back. The audit will keep finding the gap.
What good looks like
A working data classification programme has three properties, and none of them are the seven tier schema. Three categories documented in two pages and taught to every new hire in the first week. Labels applied at the point of creation, travelling with the data as metadata, driving the IAM policies the access control team enforces. An annual audit that validates the labels, reports the state to the board, and produces the artefact the regulator will look for. A good programme is also boring, and that is the point. The programme serves as the structure the data platform org uses, the framework the security org reports against, and the artefact the audit team validates. The conference talk about it is usually the tell that it is not actually working.
The bottom line
Pick the minimum useful schema, document it in two pages, apply it at creation. That is the whole programme. The teams doing this well picked the boring version and made it stick. The teams doing this poorly are still debating the seventh tier, and the audit is still finding the gap.
Sources & Further Reading
All claims in this article are sourced from primary documentation, vendor advisories, and reputable security researchers.
Spotted an error? Email the editor. Corrections are issued with a visible correction note.
Editorial standards. Every article on humanrequired.org is reviewed by a human editor before publication. AI may assist with drafting or research; final editorial control is human. Read the full standards.